Table of Contents
Ask an AI system a general question and it may be able to answer using what it learned during training.
But what happens when the answer depends on a document created yesterday, an internal company policy, a private database, or information that changes frequently?
That is where retrieval-augmented generation, usually shortened to RAG, becomes useful.
Instead of expecting an AI model to know everything from memory, RAG gives it a way to retrieve relevant information first and then use that information while creating its response.
IBM describes RAG as an approach that connects an AI model with external knowledge sources so it can generate responses using additional, relevant information.
Think of the difference as taking a closed-book exam versus an open-book exam.
The AI still needs to understand the question and produce the answer. RAG simply gives it useful material to consult before responding.
Why AI Needs Information Beyond Its Training
Large language models learn patterns from large collections of data during training.
That gives them broad knowledge, but training data has limits.
Information changes. Companies update policies. Product documentation gets revised. New research appears. Businesses also have private information that would never have been included in a public AI model’s original training data.
Suppose an employee asks an AI assistant:
“What is our company’s current vacation policy?”
A general-purpose AI model should not guess.
A RAG-powered system could instead search the company’s approved HR documents, retrieve the relevant policy and provide an answer based on that material.
That makes the response more useful because it is grounded in information that actually belongs to the organization.
How Retrieval-Augmented Generation Works
The basic RAG process is easier to understand than the name suggests.
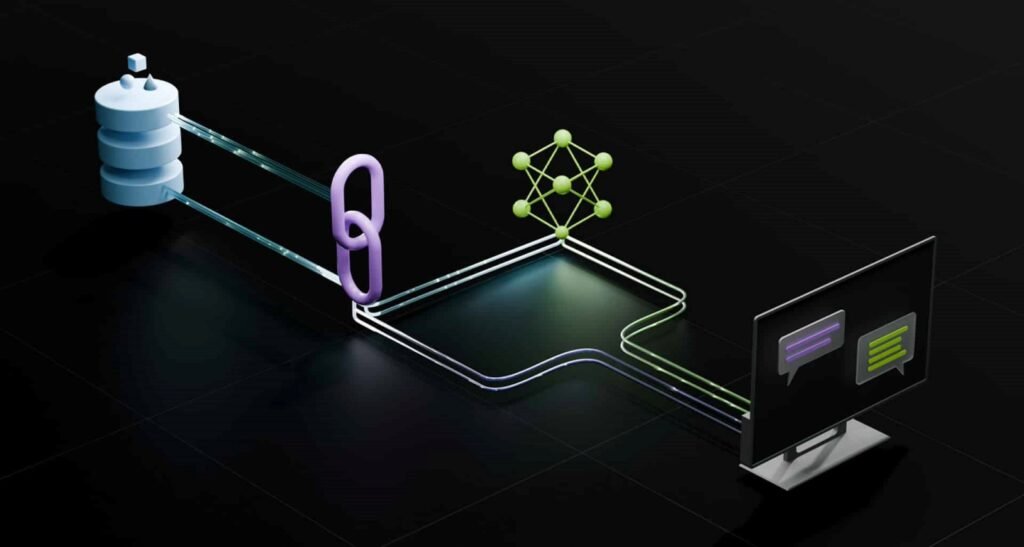
First, someone asks a question.
The system then searches an available knowledge source for information related to that question.
The retrieved information is added to the context given to the language model.
Finally, the model creates an answer using both the question and the retrieved material.
IBM describes this general process as retrieval followed by augmentation of the prompt and then generation of the response.
For the user, all of that may happen in seconds.
You simply ask the question and receive an answer.
Behind the scenes, however, the AI may have searched several pieces of information before writing a single sentence.
RAG Is Not the Same as Web Search
RAG and traditional search can work together, but they are not exactly the same thing.
A search engine generally gives you results so that you can choose which pages to open.
A RAG system retrieves information and gives selected material to an AI model, which then uses it to construct an answer.
The knowledge source does not have to be the public internet either.
It could be a collection of PDFs, internal company documents, customer-support articles, product manuals or another controlled database.
That makes RAG especially useful for businesses that want an AI assistant to work with their own information.
Why RAG Can Help Reduce AI Hallucinations
One of the biggest problems with generative AI is that a response can sound confident even when the underlying information is wrong.
Our existing AI Hallucinations article explains this problem in more detail.
RAG can help because the model is given relevant information to use instead of depending entirely on what it learned during training.
IBM notes that grounding a model in external, authoritative information can reduce hallucination risk, although it does not make the system error-proof.
That last point is important.
Retrieval improves the information available to the model.
It does not guarantee the model will interpret that information perfectly.
RAG Can Still Produce Bad Answers
Imagine that an AI system searches five documents but retrieves the wrong one.
The model may generate a polished response based on irrelevant information.
Another problem occurs when the source itself is outdated.
If an employee handbook from 2023 is retrieved instead of the current 2026 version, the AI may confidently explain a policy that is no longer valid.
This is why the quality of a RAG system depends heavily on the quality of its sources and retrieval process.
Better AI does not remove the need for good information management.
RAG, Context Windows and Prompt Engineering
RAG also connects naturally with two other AI concepts you have covered on DailyFeedNow.
The first is the AI context window.
Once information has been retrieved, some of it typically needs to fit into the context available to the model so the AI can use it while creating the response.
The second is prompt engineering.
Even when a system has excellent information available, a vague question may still produce a weak result.
Retrieving good information and asking a clear question often work together.
Why RAG Matters for Everyday AI
Most people do not need to build a retrieval system themselves to benefit from the idea.
You may already encounter AI tools that search uploaded documents, company knowledge bases or current sources before answering.
Understanding RAG helps explain why some AI systems can answer questions about information they were never originally trained on.
The model does not necessarily “know” the new information permanently.
It may simply retrieve the information when it is needed and use it for that particular response.
Final Takeaway
Retrieval-augmented generation gives AI access to relevant external information before it generates an answer.
Instead of relying only on training data, the system can search a knowledge source, bring useful information into the conversation and then create a response grounded in that material.
RAG can make AI more useful for current information, private documents and specialized knowledge.
But it does not eliminate mistakes.
Good sources, accurate retrieval and human verification still matter.